CONTACT US: Этот адрес электронной почты защищен от спам-ботов. У вас должен быть включен JavaScript для просмотра.
Заявка на патент США № 64/136,443 – USPTO
K.O.R.J.
C.O.D.E
1
C.O.D.E
METHOD
ВЫСВОБОЖДЕНИЕ МИНУСОМ
Второе действие в буквенном счёте · пять (5) пунктов
Стивен Корж · 2026
Здесь одно арифметическое действие, числа, которые оно даёт, три (3) границы, за которые оно не заходит, и программа, которой всё это считано. Пункты первый (1), второй (2) и четвёртый (4) проверяются письменно, кроме одной строки, где названо, сколько словоформ стоит при одной сумме. Пункт третий (3) — прогоном программы из пункта пятого (5): счёт там идёт по одному миллиарду шестистам восьмидесяти двум миллионам шестистам шестидесяти семи тысячам шестидесяти шести (1 682 667 066) парам, а столько на бумаге не считает никто.
1 · ДЕЙСТВИЕ
Буквенные числа больше тысячи (1000) лет складывали. Возьмите то же слово и ту же таблицу значений, но вместо сложения сделайте вот что.
Выпишите числовые значения букв слова. Оставьте каждое различное значение один (1) раз. Расположите по убыванию. Вычтите соседей сверху вниз.
Первая полученная разность называется ОПОРОЙ. Число полученных разностей называется ГЛУБИНОЙ. Ничего больше не переменилось: ни таблица, ни значения, ни порядок букв — только последнее действие.
Если все буквы слова несут одно и то же значение, различное значение у него одно (1), и вычитать не из чего: опоры нет, глубина равна нулю (0). Такие слова из счёта не выбрасываются, и два (2) слова без опоры считаются совпавшими по опоре. Таких слов в списке двадцать одно (21), а пар между ними двести десять (210) — двенадцать миллионных (0,000012) процента от всех пар списка. Если то же правило переменить и два (2) «нет опоры» совпадением не считать, фон опоры на том же списке остаётся тем же до третьего (3) знака: четыре целых восемьсот шестьдесят одна тысячная (4,861) процента.
2 · ЗНАЧЕНИЯ БУКВ
алеф 1 · бет 2 · гимель 3 · далет 4 · хе 5 · вав 6 · зайин 7 · хет 8 · тет 9 · йод 10 · каф 20 · ламед 30 · мем 40 · нун 50 · самех 60 · айин 70 · пе 80 · цади 90 · коф 100 · реш 200 · шин 300 · тав 400.
Конечные формы ך ם ן ף ץ считаются как обычные буквы: двадцать (20), сорок (40), пятьдесят (50), восемьдесят (80), девяносто (90).
Пример, чтобы проверить. נחש, змей: пятьдесят (50), восемь (8), триста (300). По убыванию: 300, 50, 8. Опора двести пятьдесят (250), глубина два (2). משיח, помазанник: сорок (40), триста (300), десять (10), восемь (8). По убыванию: 300, 40, 10, 8. Опора двести шестьдесят (260), глубина три (3). Суммы у обоих триста пятьдесят восемь (358).
3 · ЧИСЛА НА СПИСКЕ СЛОВ
Взято пятьдесят восемь тысяч двенадцать (58 012) самых частых еврейских словоформ. Список приходит с общедоступной библиотекой wordfreq версии 3.1.1: язык he, функция top_n_list, верхние шестьдесят тысяч (60 000) записей, отобраны только знаки основного ряда длиной от двух (2), повторы сняты. Список этот общедоступный и современный на сегодняшний день, я его не составлял: он приходит с библиотекой как есть.
Между этими словоформами один миллиард шестьсот восемьдесят два миллиона шестьсот шестьдесят семь тысяч шестьдесят шесть (1 682 667 066) пар. Пар, у которых суммы равны, — два миллиона двести тридцать одна тысяча триста семьдесят две (2 231 372).
Три (3) числа на каждый прибор. РАЗВЕЛА — доля пар равной суммы, у которых величина оказалась разной. ФОН — доля совпадений среди всех пар списка подряд, без всякого отбора по сумме. ПОДЪЁМ — доля совпадений при равных суммах, делённая на фон; иначе говоря, во сколько раз равенство сумм повышает совпадение.
прибор развела фон подъём
опора 82,2 % 4,861 % 3,7
глубина 70,2 % 25,125 % 1,2
обе вместе 93,1 % 1,328 % 5,2
Проверка при закреплённой длине слова. Пар, у которых равны и сумма, и длина, — пятьсот пятьдесят девять тысяч триста шестьдесят (559 360). Опора разводит из них семьдесят четыре и восемь десятых (74,8) процента, а фон здесь берётся не общий, а среди пар равной длины, и равен пяти целым ста пятидесяти тысячным (5,150) процента. Подъём выходит четыре и девять десятых (4,9) — выше, чем три и семь десятых (3,7) без закрепления длины.
Слова «среди всех пар списка подряд» в определении фона взяты точно. Если считать фон только по парам с разными суммами, он выйдет иным. Оба прочтения при одной и той же точности, в три (3) знака после запятой, стоят рядом.
фон все пары разные суммы разница
опора 4,861 % 4,844 % 0,017
глубина 25,125 % 25,119 % 0,006
обе вместе 1,328 % 1,320 % 0,008
Разница у всех трёх (3) меньше двух (2) сотых. Программа печатает обе колонки и разницу между ними.
4 · ТРИ (3) ГРАНИЦЫ
Первая (1). Опора разводит не всегда широко. אחד, один, и אהבה, любовь: суммы по тринадцать (13), опоры четыре (4) и три (3) — разница в единицу (1). Глубина же у обоих два (2) и не разводит их вовсе.
Вторая (2). При одной сумме может стоять несколько слов, и опора разведёт не всех. При сумме триста девяносто пять (395) в списке стоит восемьдесят две (82) словоформы. Возьмём три (3) из них: שופט, судья, опора двести двадцать (220); שלטון, власть, опора двести пятьдесят (250); נשמה, душа, опора двести пятьдесят (250). Судью опора отделяет, а власть и душу не разводит: у них одна опора на двоих (2). Их разводит глубина, четыре (4) и три (3).
Третья (3). Порядок букв и повторы это действие не читает. משה и השם — одни и те же три (3) значения: триста (300), сорок (40), пять (5). Опора у обоих двести шестьдесят (260), глубина у обоих два (2). Их не разводит ни сложение, ни вычитание. Повтор буквы оно не читает так же: ים, море, и מים, вода, — набор значений у обоих один и тот же, сорок (40) и десять (10), опора у обоих тридцать (30), глубина у обоих одна (1). Их разводит только сумма, пятьдесят (50) и девяносто (90).
5 · КОД
Ниже вся программа, какой посчитано всё вышестоящее. Поставьте библиотеку, сохраните строки в файл, запустите. Она печатает те же числа, что стоят выше, и ничего сверх них.
# -*- coding: utf-8 -*-
# МИНУС · весь счёт короткой статьи
# pip install wordfreq==3.1.1
from wordfreq import top_n_list
from collections import Counter
# AZ идёт по юникоду: א ב ג ד ה ו ז ח ט י ך כ ל ם מ ן נ ס ע ף פ ץ צ ק ר ש ת
# В юникоде КОНЕЧНАЯ форма стоит ПЕРЕД обычной: ך перед כ, ם перед מ,
# ן перед נ, ף перед פ, ץ перед צ. Оттого в ZN пять значений идут парами:
# 20 20 · 40 40 · 50 50 · 80 80 · 90 90 — конечная и обычная, одно и то же.
AZ = [chr(c) for c in range(0x05D0, 0x05EB)] # 27 знаков ряда
ZN = [1,2,3,4,5,6,7,8,9,10,20,20,30,40,40,50,50,
60,70,80,80,90,90,100,200,300,400] # конечные равны обычным
VAL = dict(zip(AZ, ZN))
def mery(w):
z = [VAL[c] for c in w]
u = sorted(set(z), reverse=True)
return (sum(z), # сумма
u[0] - u[1] if len(u) > 1 else None, # опора
len(u) - 1, # глубина
len(w)) # длина
seen, W = set(), []
for w in top_n_list('he', 60000):
if len(w) >= 2 and all(c in VAL for c in w) and w not in seen:
seen.add(w); W.append(w)
M = [mery(w) for w in W]
par = lambda n: n * (n - 1) // 2
vse = par(len(W))
slito = lambda kk: sum(par(v) for v in
Counter(tuple(m[k] for k in kk) for m in M).values())
print('словоформ', len(W), '· всех пар', vse)
ravn = slito([0]); print('пар равной суммы', ravn)
print(' прибор развела фон подъём')
for kk, imya in [([0,1],'опора'), ([0,2],'глубина'), ([0,1,2],'обе вместе')]:
razvela = 100 * (1 - slito(kk) / ravn) # доля разведённых пар
fon = 100 * slito(kk[1:]) / vse # доля совпавших среди ВСЕХ пар
print(' %-11s %5.1f %% %6.3f %% %.1f'
% (imya, razvela, fon, (100 - razvela) / fon))
# то же при закреплённой длине: и пары, и фон берутся только среди равнодлинных
dl = slito([0,3])
razvela = 100 * (1 - slito([0,1,3]) / dl)
fon = 100 * slito([1,3]) / slito([3])
print('пар равной суммы и равной длины', dl)
print(' %-11s %5.1f %% %6.3f %% %.1f'
% ('опора', razvela, fon, (100 - razvela) / fon))
# второе чтение слова «фон»: только пары с РАЗНЫМИ суммами
print('фон при двух прочтениях, все числа с тремя знаками после запятой:')
print(' прибор все пары разные суммы разница')
for kk, imya in [([1],'опора'), ([2],'глубина'), ([1,2],'обе вместе')]:
# колонки округляются до трёх знаков, и разница берётся между ними же,
# чтобы всякое число таблицы получалось из двух соседних
a = round(100 * slito(kk) / vse, 3)
b = round(100 * (slito(kk) - slito([0]+kk)) / (vse - ravn), 3)
print(' %-11s %8.3f %% %11.3f %% %9.3f' % (imya, a, b, round(a - b, 3)))
bez = [m for m in M if m[1] is None]
print('слов без опоры', len(bez), '· пар между ними', par(len(bez)),
'· доля %.6f %%' % (100 * par(len(bez)) / vse))
c1 = Counter(m[1] for m in M)
print('фон опоры, если «нет опоры» совпадением не считать: %.3f %%'
% (100 * sum(par(v) for k, v in c1.items() if k is not None) / vse))
print('словоформ при сумме 395', sum(1 for m in M if m[0] == 395))
ЧТО ЗДЕСЬ НЕ СКАЗАНО
Что эти разности значат. Почему опора у одних слов совпадает, а у других нет. Откуда взялось ещё одно действие и кто им считал прежде. Ловит ли оно родство там, где родство есть, — и каким опытом это меряется.
Ответы собраны в мини-книге «ВЫСВОБОЖДЕНИЕ МИНУСОМ».
ПРИГЛАШЕНИЕ
Числа открыты все до последнего. Программа напечатана целиком. Таблица значений лежит в любом справочнике.
Считайте. Ставьте свои проверки. Три (3) места, где действие разводит слабо или не разводит вовсе, стоят в пункте четвёртом (4) — начинайте оттуда.
В мини-книге лежит и самая подробная критика этой работы, какая была написана, и ответ на неё.
Заявка на патент США № 64/136,443 – USPTO
СМОТРИТЕ! СЧИТЫВАЙТЕ! СЧИТАЙТЕ!
ВПЕРЁД, НАЗАД, ВПЕРЁД!
Стивен Корж
Слава МЦЦ
STEVENKORJ.COM | Этот адрес электронной почты защищен от спам-ботов. У вас должен быть включен JavaScript для просмотра. | 1UFO.INFO
2--------------------------------------------------------------------------------------------------------
3--------------------------------------------------------------------------------------------------------
4--------------------------------------------------------------------------------------------------------
5--------------------------------------------------------------------------------------------------------
6--------------------------------------------------------------------------------------------------------
7--------------------------------------------------------------------------------------------------------
8--------------------------------------------------------------------------------------------------------
9--------------------------------------------------------------------------------------------------------
10------------------------------------------------------------------------------------------------------
CONTACT US: Этот адрес электронной почты защищен от спам-ботов. У вас должен быть включен JavaScript для просмотра.
U.S. Patent Application No. 64/136,443 – USPTO
K.O.R.J.
C.O.D.E
1
C.O.D.E
METHOD
LIBERATION THROUGH THE MINUS
The second action in letter counting · five (5) points
Steven Korj · 2026
Here is one arithmetical action, the numbers it gives, three (3) limits it does not cross, and the program by which all of this was counted. Points one (1), two (2) and four (4) are open to a check right here in the text, except for one line, where it is stated how many word forms stand at one sum. Point three (3) is checked by a run of the program from point five (5): the count there goes over one billion six hundred eighty-two million six hundred sixty-seven thousand sixty-six (1,682,667,066) pairs, and nobody counts that many on paper.
1 · THE ACTION
Letter numbers were added up for more than a thousand (1000) years. Take the same word and the same table of values, but instead of addition do this.
Write out the numerical values of the letters of the word. Keep each distinct value once (1). Arrange them in descending order. Subtract the neighbours from top to bottom.
The first difference obtained is called the SUPPORT. The number of differences obtained is called the DEPTH. Nothing else has changed: not the table, not the values, not the order of the letters — only the last action.
If all the letters of a word carry one and the same value, it has one (1) distinct value, and there is nothing to subtract from: there is no support, the depth equals zero (0). Such words are not thrown out of the count, and two (2) words without a support are counted as matching by support. There are twenty-one (21) such words in the list, and two hundred ten (210) pairs among them — twelve millionths (0.000012) of a percent of all the pairs of the list. If that same rule is changed and two (2) "no support" are not counted as a match, the background of the support on the same list stays the same to the third (3) decimal place: four and eight hundred sixty-one thousandths (4.861) percent.
2 · THE VALUES OF THE LETTERS
alef 1 · bet 2 · gimel 3 · dalet 4 · he 5 · vav 6 · zayin 7 · chet 8 · tet 9 · yod 10 · kaf 20 · lamed 30 · mem 40 · nun 50 · samekh 60 · ayin 70 · pe 80 · tsadi 90 · qof 100 · resh 200 · shin 300 · tav 400.
The final forms ך ם ן ף ץ count as the ordinary letters: twenty (20), forty (40), fifty (50), eighty (80), ninety (90).
An example, to check. נחש, serpent: fifty (50), eight (8), three hundred (300). In descending order: 300, 50, 8. The support is two hundred fifty (250), the depth is two (2). משיח, the anointed one: forty (40), three hundred (300), ten (10), eight (8). In descending order: 300, 40, 10, 8. The support is two hundred sixty (260), the depth is three (3). The sums of both are three hundred fifty-eight (358).
3 · THE NUMBERS ON A LIST OF WORDS
Fifty-eight thousand twelve (58,012) of the most frequent Hebrew word forms are taken. The list comes with the publicly available library wordfreq, version 3.1.1: language he, function top_n_list, the top sixty thousand (60,000) entries, only those made of the signs of the basic row, with a length from two (2) up, were selected, repeats removed. This list is publicly available and current as of today, I did not compile it: it comes with the library as it is.
Between these word forms there are one billion six hundred eighty-two million six hundred sixty-seven thousand sixty-six (1,682,667,066) pairs. The pairs whose sums are equal are two million two hundred thirty-one thousand three hundred seventy-two (2,231,372).
Three (3) numbers for each gauge. SEPARATED — the share of the pairs of equal sum in which the value came out different. BACKGROUND — the share of matches among all the pairs of the list taken whole, without any selection by sum. LIFT — the share of matches at equal sums, divided by the background; in other words, how many times the equality of the sums raises the match.
gauge separated background lift
support 82.2 % 4.861 % 3.7
depth 70.2 % 25.125 % 1.2
both together 93.1 % 1.328 % 5.2
A check with the length of the word fixed. The pairs in which both the sum and the length are equal are five hundred fifty-nine thousand three hundred sixty (559,360). The support separates seventy-four and eight tenths (74.8) percent of them, and the background here is taken not as the general one but among the pairs of equal length, and equals five and one hundred fifty thousandths (5.150) percent. The lift comes out as four and nine tenths (4.9) — higher than three and seven tenths (3.7) without the length fixed.
The words "among all the pairs of the list taken whole" in the definition of the background are taken exactly. If the background is counted only over the pairs with different sums, it comes out otherwise. Both readings, at one and the same precision of three (3) decimal places, stand side by side.
background all pairs different sums difference
support 4.861 % 4.844 % 0.017
depth 25.125 % 25.119 % 0.006
both together 1.328 % 1.320 % 0.008
The difference in all three (3) is less than two (2) hundredths. The program prints both columns and the difference between them.
4 · THREE (3) LIMITS
The first (1). The support does not always separate widely. אחד, one, and אהבה, love: the sums are thirteen (13) each, the supports are four (4) and three (3) — a difference of one (1). The depth of both is two (2) and does not separate them at all.
The second (2). Several words can stand at one sum, and the support will not separate them all. At the sum three hundred ninety-five (395) there are eighty-two (82) word forms in the list. Let us take three (3) of them: שופט, judge, support two hundred twenty (220); שלטון, power, support two hundred fifty (250); נשמה, soul, support two hundred fifty (250). The judge is set apart by the support, but the power and the soul it does not separate: they have one support for the two (2) of them. They are separated by the depth, four (4) and three (3).
The third (3). The order of the letters and the repeats this action does not read. משה and השם — one and the same three (3) values: three hundred (300), forty (40), five (5). The support of both is two hundred sixty (260), the depth of both is two (2). Neither addition nor subtraction separates them. A repeated letter it does not read either: ים, sea, and מים, water, — the set of values of both is one and the same, forty (40) and ten (10), the support of both is thirty (30), the depth of both is one (1). They are separated only by the sum, fifty (50) and ninety (90).
5 · THE CODE
Below is the whole program by which everything above was counted. Install the library, save the lines into a file, run it. It prints the same numbers that stand above, and nothing beyond them.
# -*- coding: utf-8 -*-
# MINUS · the whole count of the short article
# pip install wordfreq==3.1.1
from wordfreq import top_n_list
from collections import Counter
# AZ runs in Unicode order: א ב ג ד ה ו ז ח ט י ך כ ל ם מ ן נ ס ע ף פ ץ צ ק ר ש ת
# In Unicode the FINAL form stands BEFORE the ordinary one: ך before כ, ם before מ,
# ן before נ, ף before פ, ץ before צ. That is why five values in ZN go in pairs:
# 20 20 · 40 40 · 50 50 · 80 80 · 90 90 — the final and the ordinary, one and the same.
AZ = [chr(c) for c in range(0x05D0, 0x05EB)] # 27 signs of the row
ZN = [1,2,3,4,5,6,7,8,9,10,20,20,30,40,40,50,50,
60,70,80,80,90,90,100,200,300,400] # the finals equal the ordinary ones
VAL = dict(zip(AZ, ZN))
def mery(w):
z = [VAL[c] for c in w]
u = sorted(set(z), reverse=True)
return (sum(z), # sum
u[0] - u[1] if len(u) > 1 else None, # support
len(u) - 1, # depth
len(w)) # length
seen, W = set(), []
for w in top_n_list('he', 60000):
if len(w) >= 2 and all(c in VAL for c in w) and w not in seen:
seen.add(w); W.append(w)
M = [mery(w) for w in W]
par = lambda n: n * (n - 1) // 2
vse = par(len(W))
slito = lambda kk: sum(par(v) for v in
Counter(tuple(m[k] for k in kk) for m in M).values())
print('word forms', len(W), '· all pairs', vse)
ravn = slito([0]); print('pairs of equal sum', ravn)
print(' gauge separated background lift')
for kk, imya in [([0,1],'support'), ([0,2],'depth'), ([0,1,2],'both together')]:
razvela = 100 * (1 - slito(kk) / ravn) # share of the separated pairs
fon = 100 * slito(kk[1:]) / vse # share of the matches among ALL pairs
print(' %-13s %5.1f %% %6.3f %% %.1f'
% (imya, razvela, fon, (100 - razvela) / fon))
# the same with the length fixed: pairs and background only among equal-length words
dl = slito([0,3])
razvela = 100 * (1 - slito([0,1,3]) / dl)
fon = 100 * slito([1,3]) / slito([3])
print('pairs of equal sum and equal length', dl)
print(' %-13s %5.1f %% %6.3f %% %.1f'
% ('support', razvela, fon, (100 - razvela) / fon))
# the second reading of the word "background": only the pairs with DIFFERENT sums
print('background under two readings, all numbers to three decimal places:')
print(' gauge all pairs different sums difference')
for kk, imya in [([1],'support'), ([2],'depth'), ([1,2],'both together')]:
# the columns are rounded to three places, and the difference is taken between them,
# so that every number of the table follows from its two neighbours
a = round(100 * slito(kk) / vse, 3)
b = round(100 * (slito(kk) - slito([0]+kk)) / (vse - ravn), 3)
print(' %-13s %8.3f %% %11.3f %% %9.3f' % (imya, a, b, round(a - b, 3)))
bez = [m for m in M if m[1] is None]
print('words with no support', len(bez), '· pairs among them', par(len(bez)),
'· share %.6f %%' % (100 * par(len(bez)) / vse))
c1 = Counter(m[1] for m in M)
print('background of the support if "no support" is not counted as a match: %.3f %%'
% (100 * sum(par(v) for k, v in c1.items() if k is not None) / vse))
print('word forms at the sum 395', sum(1 for m in M if m[0] == 395))
WHAT IS NOT SAID HERE
What these differences mean. Why the support of some words coincides and of others does not. Where one more action came from and who counted with it before. Whether it catches kinship where kinship is there — and by what experiment that is measured.
The answers are gathered in the mini-book "LIBERATION THROUGH THE MINUS".
THE INVITATION
The numbers are open, all of them to the last. The program is printed in full. The table of values lies in any reference book.
Count. Set your own checks. The three (3) places where the action separates weakly or does not separate at all stand in point four (4) — start from there.
The mini-book also holds the most detailed criticism of this work that has been written, and the answer to it.
Dear readers, this article is published in its original language on Zenodo.
Link: K.O.R.J. C.O.D.E 1 C.O.D.E: Высвобождение Минусом | Zenodo
U.S. Patent Application No. 64/136,443 – USPTO
LOOK! READ! COUNT!
FORWARD, BACK, FORWARD!
Steven Korj
Slava MCC
STEVENKORJ.COM | Этот адрес электронной почты защищен от спам-ботов. У вас должен быть включен JavaScript для просмотра. | 1UFO.INFO
2--------------------------------------------------------------------------------------------------------
3--------------------------------------------------------------------------------------------------------
4--------------------------------------------------------------------------------------------------------
5--------------------------------------------------------------------------------------------------------
6--------------------------------------------------------------------------------------------------------
7--------------------------------------------------------------------------------------------------------
8--------------------------------------------------------------------------------------------------------
9--------------------------------------------------------------------------------------------------------
10-------------------------------------------------------------------------------------------------------
CONTACT US: Этот адрес электронной почты защищен от спам-ботов. У вас должен быть включен JavaScript для просмотра.
Patent Pending – U.S. Application No. 64/136,443
Patente Pendente – Pedido nº 64/136,443 – USPTO
K.O.R.J.
C.O.D.E
1
C.O.D.E
METHOD
LIBERAÇÃO PELO SINAL DE MENOS
A segunda operação na conta das letras · cinco (5) pontos
Steven Korj · 2026
Aqui está uma operação aritmética, os números que ela dá, três (3) limites que ela não ultrapassa, e o programa com que tudo isso foi calculado. Os pontos primeiro (1), segundo (2) e quarto (4) se verificam no papel, exceto uma linha, em que se diz quantas formas de palavra estão sob uma mesma soma. O ponto terceiro (3) — pela execução do programa do ponto quinto (5): ali a conta corre por um bilhão seiscentos e oitenta e dois milhões seiscentos e sessenta e sete mil e sessenta e seis (1 682 667 066) pares, e uma conta dessas ninguém faz no papel.
1 · A OPERAÇÃO
Há mais de mil (1000) anos os números das letras vêm sendo somados. Tome a mesma palavra e a mesma tabela de valores, mas em vez de somar, faça o seguinte.
Escreva os valores numéricos das letras da palavra. Deixe cada valor diferente aparecer uma (1) vez. Coloque-os em ordem decrescente. Subtraia os vizinhos de cima para baixo.
A primeira diferença obtida chama-se APOIO. O número de diferenças obtidas chama-se PROFUNDIDADE. Nada mais mudou: nem a tabela, nem os valores, nem a ordem das letras — só a última operação.
Se todas as letras da palavra têm o mesmo valor, o valor diferente nela é um (1) só, e não há o que subtrair: apoio não há, e a profundidade é igual a zero (0). Essas palavras não são descartadas da conta, e duas (2) palavras sem apoio contam como coincidentes no apoio. Palavras assim há vinte e uma (21) na lista, e pares entre elas duzentos e dez (210) — doze milionésimos (0,000012) por cento de todos os pares da lista. Se essa mesma regra for mudada e dois (2) «sem apoio» não contarem como coincidência, o fundo do apoio na mesma lista permanece o mesmo até a terceira (3) casa: quatro inteiros e oitocentos e sessenta e um milésimos (4,861) por cento.
2 · OS VALORES DAS LETRAS
alef 1 · bet 2 · gimel 3 · dalet 4 · he 5 · vav 6 · zayin 7 · het 8 · tet 9 · yod 10 · kaf 20 · lamed 30 · mem 40 · nun 50 · samech 60 · ayin 70 · pe 80 · tsadi 90 · kof 100 · resh 200 · shin 300 · tav 400.
As formas finais ך ם ן ף ץ contam como as letras comuns: vinte (20), quarenta (40), cinquenta (50), oitenta (80), noventa (90).
Um exemplo, para conferir. נחש, serpente: cinquenta (50), oito (8), trezentos (300). Em ordem decrescente: 300, 50, 8. Apoio duzentos e cinquenta (250), profundidade dois (2). משיח, ungido: quarenta (40), trezentos (300), dez (10), oito (8). Em ordem decrescente: 300, 40, 10, 8. Apoio duzentos e sessenta (260), profundidade três (3). A soma em ambos é trezentos e cinquenta e oito (358).
3 · OS NÚMEROS NA LISTA DE PALAVRAS
Foram tomadas cinquenta e oito mil e doze (58 012) das formas de palavra hebraicas mais frequentes. A lista vem da biblioteca pública wordfreq, versão 3.1.1: língua he, função top_n_list, os sessenta mil (60 000) primeiros registros, mantidas só as palavras escritas com os sinais da fileira principal, de comprimento a partir de dois (2), repetições retiradas. Essa lista é pública e atual; eu não a compus: ela vem com a biblioteca como está.
Entre essas formas de palavra há um bilhão seiscentos e oitenta e dois milhões seiscentos e sessenta e sete mil e sessenta e seis (1 682 667 066) pares. Pares cujas somas são iguais — dois milhões duzentos e trinta e um mil trezentos e setenta e dois (2 231 372).
Três (3) números para cada instrumento. SEPAROU — a fração dos pares de soma igual em que a grandeza saiu diferente. FUNDO — a fração de coincidências entre todos os pares da lista, indistintamente, sem nenhuma escolha pela soma. ELEVAÇÃO — a fração de coincidências sob somas iguais, dividida pelo fundo; ou seja, quantas vezes a igualdade das somas aumenta a coincidência.
instrumento separou fundo elevação
apoio 82,2 % 4,861 % 3,7
profundidade 70,2 % 25,125 % 1,2
os dois juntos 93,1 % 1,328 % 5,2
Verificação com o comprimento da palavra fixado. Pares em que são iguais tanto a soma quanto o comprimento — quinhentos e cinquenta e nove mil trezentos e sessenta (559 360). O apoio separa setenta e quatro e oito décimos (74,8) por cento deles, e o fundo aqui não é o geral, mas o calculado entre os pares de igual comprimento, e vale cinco inteiros e cento e cinquenta milésimos (5,150) por cento. A elevação sai quatro e nove décimos (4,9) — mais alta que os três e sete décimos (3,7) sem o comprimento fixado.
As palavras «entre todos os pares da lista, indistintamente» na definição do fundo são tomadas ao pé da letra. Se o fundo for contado só pelos pares de somas diferentes, ele sai outro. As duas leituras, na mesma precisão, em três (3) casas depois da vírgula, estão aqui lado a lado.
fundo todos os pares somas diferentes diferença
apoio 4,861 % 4,844 % 0,017
profundidade 25,125 % 25,119 % 0,006
os dois juntos 1,328 % 1,320 % 0,008
A diferença nos três (3) é menor que dois (2) centésimos. O programa imprime as duas colunas e a diferença entre elas.
4 · TRÊS (3) LIMITES
Primeiro (1). O apoio nem sempre separa com folga. אחד, um, e אהבה, amor: somas de treze (13) cada, apoios quatro (4) e três (3) — diferença de uma (1) unidade. Já a profundidade nos dois é dois (2) e não os separa de modo nenhum.
Segundo (2). Sob uma mesma soma podem estar várias palavras, e o apoio não separa todas. Sob a soma trezentos e noventa e cinco (395) estão na lista oitenta e duas (82) formas de palavra. Tomemos três (3) delas: שופט, juiz, apoio duzentos e vinte (220); שלטון, poder, apoio duzentos e cinquenta (250); נשמה, alma, apoio duzentos e cinquenta (250). O apoio separa o juiz dos outros dois, mas não separa poder e alma: os dois (2) têm o mesmo apoio. Já a profundidade os separa: quatro (4) e três (3).
Terceiro (3). Esta operação não lê a ordem das letras nem as repetições. משה e השם — os mesmos três (3) valores: trezentos (300), quarenta (40), cinco (5). O apoio nos dois é duzentos e sessenta (260), a profundidade nos dois é dois (2). Nem a adição nem a subtração os separam. Ela também não lê a repetição de uma letra: ים, mar, e מים, água — o conjunto de valores nos dois é o mesmo, quarenta (40) e dez (10), o apoio nos dois é trinta (30), a profundidade nos dois é um (1). Só a soma os separa: cinquenta (50) e noventa (90).
5 · O CÓDIGO
Abaixo está todo o programa com que foi calculado tudo o que está acima. Instale a biblioteca, salve as linhas num arquivo, execute. Ele imprime os mesmos números que estão acima, e nada além deles.
# -*- coding: utf-8 -*-
# MENOS · toda a conta do artigo curto
# pip install wordfreq==3.1.1
from wordfreq import top_n_list
from collections import Counter
# AZ segue a ordem do unicode: א ב ג ד ה ו ז ח ט י ך כ ל ם מ ן נ ס ע ף פ ץ צ ק ר ש ת
# No unicode a forma FINAL vem ANTES da comum: ך antes de כ, ם antes de מ,
# ן antes de נ, ף antes de פ, ץ antes de צ. Por isso em VN cinco valores aparecem aos pares:
# 20 20 · 40 40 · 50 50 · 80 80 · 90 90 — final e comum, o mesmo valor.
AZ = [chr(c) for c in range(0x05D0, 0x05EB)] # 27 sinais da fileira
VN = [1,2,3,4,5,6,7,8,9,10,20,20,30,40,40,50,50,
60,70,80,80,90,90,100,200,300,400] # finais iguais as comuns
VAL = dict(zip(AZ, VN))
def medidas(p):
z = [VAL[c] for c in p]
u = sorted(set(z), reverse=True)
return (sum(z), # soma
u[0] - u[1] if len(u) > 1 else None, # apoio
len(u) - 1, # profundidade
len(p)) # comprimento
vistas, W = set(), []
for p in top_n_list('he', 60000):
if len(p) >= 2 and all(c in VAL for c in p) and p not in vistas:
vistas.add(p); W.append(p)
M = [medidas(p) for p in W]
par = lambda n: n * (n - 1) // 2
todos = par(len(W))
juntos = lambda kk: sum(par(v) for v in
Counter(tuple(m[k] for k in kk) for m in M).values())
print('formas de palavra', len(W), '· pares no total', todos)
iguais = juntos([0]); print('pares de soma igual', iguais)
print(' instrumento separou fundo elevacao')
for kk, nome in [([0,1],'apoio'), ([0,2],'profundidade'), ([0,1,2],'os dois juntos')]:
separou = 100 * (1 - juntos(kk) / iguais) # fracao de pares separados
fundo = 100 * juntos(kk[1:]) / todos # coincidencias entre TODOS os pares
print(' %-14s %5.1f %% %6.3f %% %.1f'
% (nome, separou, fundo, (100 - separou) / fundo))
# o mesmo com o comprimento fixado: pares e fundo so entre palavras de igual comprimento
cmp = juntos([0,3])
separou = 100 * (1 - juntos([0,1,3]) / cmp)
fundo = 100 * juntos([1,3]) / juntos([3])
print('pares de soma igual e comprimento igual', cmp)
print(' %-14s %5.1f %% %6.3f %% %.1f'
% ('apoio', separou, fundo, (100 - separou) / fundo))
# segunda leitura da palavra «fundo»: so os pares de somas DIFERENTES
print('fundo em duas leituras, todos os numeros com tres casas decimais:')
print(' instrumento todos os pares somas diferentes diferenca')
for kk, nome in [([1],'apoio'), ([2],'profundidade'), ([1,2],'os dois juntos')]:
# as colunas sao arredondadas a tres casas, e a diferenca e tirada entre elas,
# para que todo numero da tabela saia dos dois vizinhos
a = round(100 * juntos(kk) / todos, 3)
b = round(100 * (juntos(kk) - juntos([0]+kk)) / (todos - iguais), 3)
print(' %-14s %8.3f %% %11.3f %% %9.3f' % (nome, a, b, round(a - b, 3)))
sem = [m for m in M if m[1] is None]
print('palavras sem apoio', len(sem), '· pares entre elas', par(len(sem)),
'· fracao %.6f %%' % (100 * par(len(sem)) / todos))
cont = Counter(m[1] for m in M)
print('fundo do apoio, se «sem apoio» nao contar como coincidencia: %.3f %%'
% (100 * sum(par(v) for k, v in cont.items() if k is not None) / todos))
print('formas de palavra com soma 395', sum(1 for m in M if m[0] == 395))
O QUE NÃO ESTÁ DITO AQUI
O que essas diferenças significam. Por que o apoio coincide em umas palavras e não em outras. De onde veio mais essa operação e quem a usou antes para contar. Se ela capta o parentesco onde o parentesco existe — e com que experimento isso se mede.
As respostas estão reunidas no mini-livro «LIBERAÇÃO PELO SINAL DE MENOS — O MÉTODO RESISTIU».
CONVITE
Os números estão abertos, todos até o último. O programa está impresso por inteiro. A tabela de valores está em qualquer manual.
Conte. Faça as suas próprias verificações. Três (3) lugares onde a operação separa pouco ou não separa de modo nenhum estão no ponto quarto (4) — comece por aí.
No mini-livro está também a crítica mais detalhada que já se escreveu sobre este trabalho, e a resposta a ela até o último ponto.
Este artigo foi traduzido do original. Caros leitores, este artigo está publicado na língua original no Zenodo.
Link: K.O.R.J. C.O.D.E 1 C.O.D.E: Высвобождение Минусом | Zenodo
Patent Pending – U.S. Application No. 64/136,443
Patente Pendente – Pedido nº 64/136,443 – USPTO
PARA FRENTE, PARA TRÁS, PARA FRENTE!
Steven Korj
Slava MCC
STEVENKORJ.COM | Этот адрес электронной почты защищен от спам-ботов. У вас должен быть включен JavaScript для просмотра. | 1UFO.INFO
*****
TAKE THE LIGH ! IT'S LEGACY FROM THE ANCIENTS ! LINGUISTIC-WAVE GENETICKL !
LBREAKING NEWS! STEVEN KORJ HAS DECIPHERED THE VOYNICH MANUSCRIPT! THE "MOMENT" METHOD AND THE "AUTOSENSER" CARD - LEGACY FROM THE ANCIENTS!
ANY QUESTIONS ???
NO QUESTIONS !
NEW BOOK!
"PSIHOLOGISTIKA.COM - THE SOUL FROM ABOVE!"
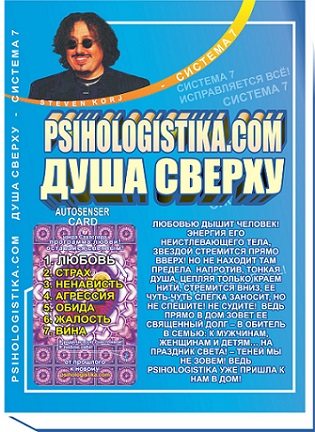
BRIEF BOOK REVIEW
"PSIHOLOGISTIKA.COM - THE SOUL FROM ABOVE"
INTRODUCTION: 6 P
AWARENESS - AND IS AN EXEMPTION !!! 14 P
ON INTENDED USE OF THIS INFORMATION. 15 P
WE ARE GETTING RID OF TOBACCO! 16 P
FORMULA OF HAPPINESS 17  P
7 PROGRAMS IS IT WITHOUT AGE! 18  P
CHAPTER 1. LIFE WITHOUT WRINKLES, TIGHTENING THE FACE, GENERAL REVOLUTION! 19 P
CHAPTER 1 - A. TRUE HISTORIES OF YOUR EXEMPTIONS. 35 P
CHAPTER 1 - B. INTRODUCTION TO THE SYSTEM OF 7 PROGRAMS AND ITS OPPORTUNITIES: 124 P
№ 1. THE PROGRAM OF LOVE !!! 124 P
№ 2. THE PROGRAM OF FEAR 126 P
№ 3. THE PROGRAM OF HATE 127 P
№ 4. THE PROGRAM OF AGGRESSION 128 P
№ 5. THE PROGRAM OF HURT 129 P
PRIDE. 129 P
LEVEL FIRST: 129 P
LEVEL SECOND: 129 P
LEVEL OF THE THIRD: 129 P
№6. THE PROGRAM OF AWAY. 134 P
№7. THE PROGRAM OF VINS. 135 P
WISH: 138 P
RECOMMENDATION: 140 P
DIARY OF YOUR CHANGES AND ADDITIONS 142 P
A LITTLE ABOUT CARDS - AUTOSENSER AND TECHNIQUE WORK ON OURSELVES 146 P
THE SCIENCE PROVED 151 P
CREATIVE VISUALIZATION 152 P
LAUGHTHERAPY OR THERAPY WITH SMILING FROM THE INSIDE. 162 P
AWARENESSED MEDITATION. STAGES OF TEACHING BRAIN CONTROL. STAGE 1. 163 P
AWARENESSED MEDITATION. STAGE 2. 171 P
A FEW WORDS ABOUT WHY PEOPLE ARE BORREL OF 173 P
MONEY, FOR HELPING PEOPLE - I DO NOT KEEP. 178 P
INVENTIONS 180 P
AWARENESSED MEDITATION. STAGE 3. 188 P
CHAPTER 2. UNSPECIFIED FEELINGS OF RECOGNIZED MEDITATION 193 P
FIRST CUSTOMER'S VISIT TO THE DOCTOR (ON PROGRAM TESTING WITH THE FRAMEWORK): 202 P
IT HAS ENTERED THE TIME OF THE SEMINAR. STORY ABOUT THE SYSTEM DEVICE 7 PROGRAMS. 215 P
THAN DIFFERENT CARDS - AUTOSENSER BETWEEN YOURSELF. 217 P
APPLICATION OF THE CARD - AUTOSENSER WITH THE IMPLEMENTATION OF IMPROVE EXERCISES: 232 P
INSTRUCTIONS FOR THE USE OF THE CARD - AUTOSENSER: 235 P
CHAPTER 3. SPIRITUAL GROWTH OR GROWTH OF YOUR CONSCIOUSNESS
(EXPANDING THE CONSCIOUSNESS) - IS NOT THE SAME AND THE SAME. 241 P
CHAPTER 4. AWARENESSED MEDITATION. INCLUDE LIGHT IN YOUR HEAD! STEP 4. 263 P
CHAPTER 5. SONASTROJKA - MAP - AUTOSENSER. 275 P
PSYCHOLOGY 277 P
IN WHAT DIFFERENCE: UNDERSTANDING AND AWARENESS OF 280 P
CHAPTER 5 - A VERSUS 281 P
CHAPTER 5 - IN OUR SELF P
«WHAT IS HAPPINESS» 296 P
CHAPTER 6. HISTORY 307 P
ENERGY OF MONEY. 397 P
AFFIRMATIONS! (FOR APPLICATION WITH CARD - AUTOSENSER) 402 P
HIT OF THE 21-ST CENTURY! STEP 5. 411 P
INSTRUCTION TO THE EXERCISE OF THE EXERCISE OF "EIGHT" 415 P
- Вы здесь:
- Главная

- Uncategorised


